POPULAR COURSES
Master Programs
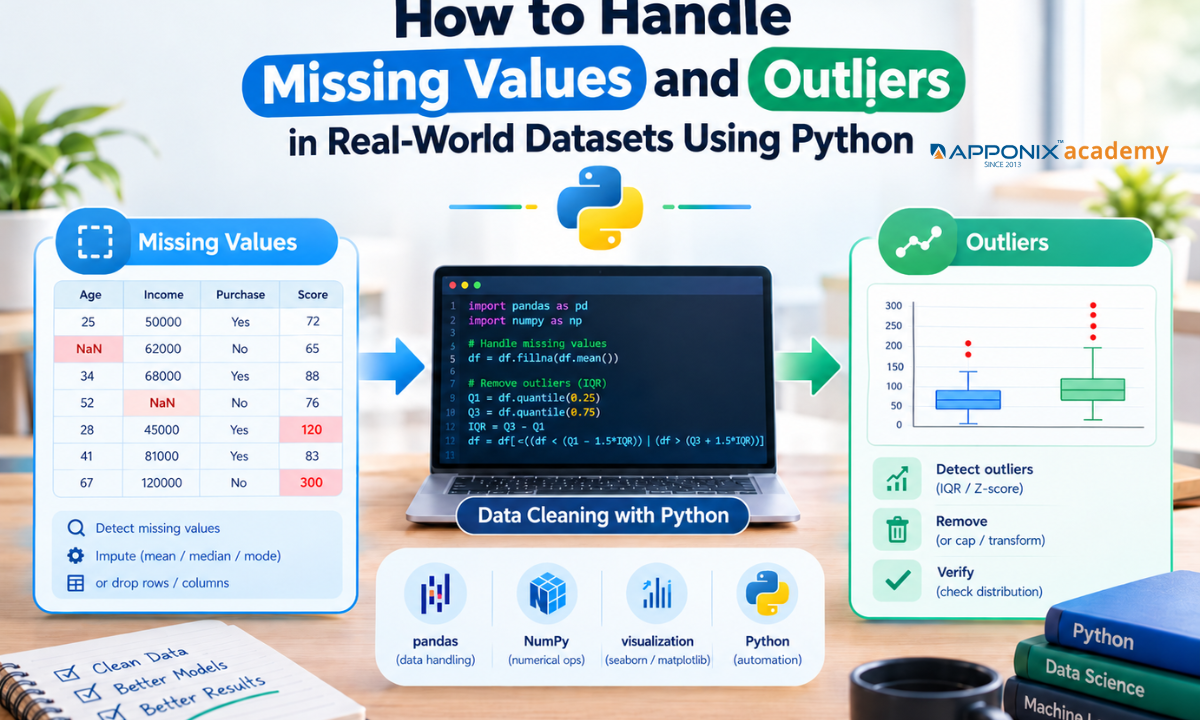
Table of contents:
|
1. Understanding Missing Values and Outliers |
|
2. Identifying Data Quality Issues Using Pandas |
|
3. Handling Missing Values in Python |
|
4. Detecting Outliers Using Python |
|
5. Choosing the Right Outlier Treatment |
|
6. Avoiding Data Leakage and Distorted Analysis |
|
7. Best Practices for Reliable Data Cleaning |
|
8. Conclusion |
Real-world datasets often contain missing values, duplicate records, incorrect entries, and unusual observations. These data quality issues can affect statistical analysis, data visualisation, and machine learning model performance. Before building a model, data scientists must identify these problems and apply suitable data preprocessing techniques.
Python provides several libraries for data cleaning, including Pandas, NumPy, Matplotlib, and Scikit-learn. These tools help identify incomplete records, detect outliers, handle missing data, and prepare reliable datasets for analysis.
This guide explains how to handle missing values and outliers using Python, with practical examples and methods that help maintain data accuracy. To go further with hands-on practice, you can explore the training programs at Apponix Technologies.
1. Understanding Missing Values and Outliers
Missing values occur when a dataset does not contain information for one or more fields. They may result from incomplete forms, failed data collection, database errors, or unavailable measurements.
For example, a customer dataset may contain missing values in the age, income, or purchase history columns.
Outliers are observations that differ considerably from the general pattern of a dataset. They may represent genuine events, measurement errors, or incorrect data entries.
Consider a dataset containing monthly salaries ranging from ₹20,000 to ₹80,000, with one entry of ₹8,00,000. This value may be correct for a senior executive or may indicate a data entry error. Further investigation is necessary before deciding how to handle it.
Both problems require careful examination. Removing data without understanding its meaning can introduce bias and reduce the reliability of analysis.
2. Identifying Data Quality Issues Using Pandas
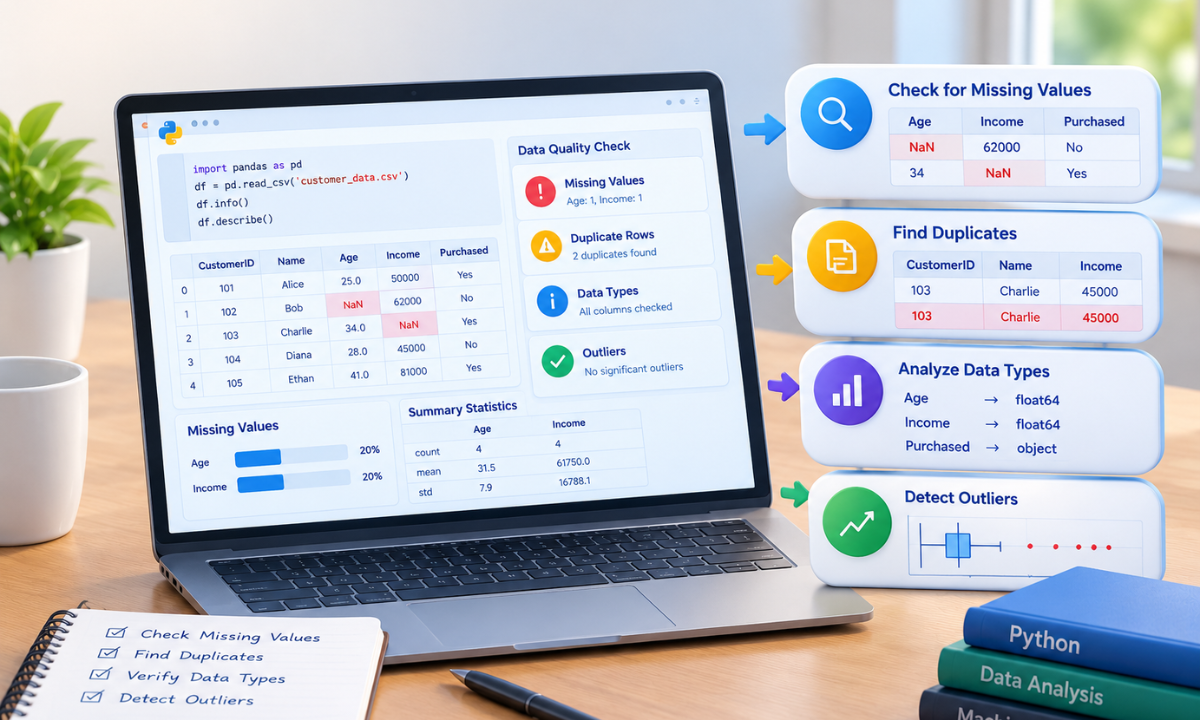
The first step in data cleaning is to understand the dataset's structure and quality. Pandas provides functions to inspect columns, identify missing values, and check data types.
import pandas as pdimport numpy as npdf = pd.read_csv("customer_data.csv")print(df.head())print(df.info())print(df.describe(include="all"))print(df.isnull().sum())print("Duplicate rows:", df.duplicated().sum())
These commands provide an overview of the dataset.
-
head() displays sample records.
-
info() shows column names, data types, and non-null counts.
-
describe() summarises numerical and categorical columns.
-
isnull().sum() counts missing values in each column.
-
duplicated().sum() identifies duplicate rows.
Check whether missing values are concentrated in specific columns or records. Also, examine whether numerical fields contain incorrect data types or unexpected values.
For example, a price column stored as text may prevent mathematical calculations. Correcting such issues before imputation helps avoid further errors.
For more background on working with datasets and analytical workflows, explore how to build an end-to-end machine learning pipeline using Scikit-learn.
3. Handling Missing Values in Python
Missing data can affect averages, correlations, and machine learning predictions. The right treatment depends on the amount of missing data, the type of variable, and the reason the information is unavailable.
Remove or retain incomplete records
Use dropna() when only a small number of records are incomplete and their removal will not affect the analysis significantly.
# Remove rows where every column is missingdf_clean = df.dropna(how="all")
# Check missing values in important columnsprint(df[["age", "income"]].isnull().sum())
Avoid deleting every row that contains a missing value without checking the impact. This can reduce the dataset size and introduce selection bias.
Use mean, median, or mode imputation
Imputation replaces missing values with estimated values. The method should match the variable and its distribution.
-
Mean imputation: Suitable for numerical data with a relatively balanced distribution and limited extreme values.
-
Median imputation: Often more suitable for skewed numerical data because extreme values have less influence on the median.
-
Mode imputation: Useful for categorical variables when the most frequent category is a reasonable replacement.
Python implementation:
# Numerical imputationdf["age"] = df["age"].fillna(df["age"].median())
# Categorical imputationdf["city"] = df["city"].fillna( df["city"].mode()[0])
These methods are simple, but they can reduce variability or distort relationships between variables. For example, filling every missing income with the median may hide differences between customer groups.
When the missingness pattern is meaningful, consider adding a missing-value indicator or using group-based or model-based imputation.
For a deeper explanation of these approaches, read How to handle missing data: best practices in data preparation.
Use Scikit-learn for consistent imputation
For machine learning projects, Scikit-learn provides SimpleImputer, which applies a chosen strategy consistently across datasets.
from sklearn.impute import SimpleImputerimputer = SimpleImputer(strategy="median")df[["age", "income"]] = imputer.fit_transform( df[["age", "income"]])
In a predictive workflow, fit the imputer on the training data and use the fitted imputer to transform validation and test data. This prevents data leakage, where information from the evaluation dataset influences model preparation.
4. Detecting Outliers Using Python
Outlier detection helps identify unusual values that may affect statistical analysis and predictive models. However, an outlier is not automatically an error. The correct treatment depends on the data source, business context, and analytical objective.
Use descriptive statistics and visualisation
Start by reviewing summary statistics and plotting the numerical distribution.
import matplotlib.pyplot as pltprint(df["income"].describe())plt.boxplot(df["income"].dropna())plt.title("Income Distribution")plt.ylabel("Income")plt.show()
A box plot highlights values beyond the usual spread of the data. It can help identify unusual observations for further investigation.
For example, an unusually high income may be valid, while a negative age value may indicate a data quality problem.
Apply the Interquartile Range (IQR) method
The IQR method is a common statistical technique for identifying potential outliers. It measures the difference between the third quartile (Q3) and the first quartile (Q1).
IQR=Q3-Q1
Values below Q1-1.5IQR or above Q3+1.5IQR are flagged as potential outliers.
Q1 = df["income"].quantile(0.25)Q3 = df["income"].quantile(0.75)IQR = Q3 - Q1lower_bound = Q1 - 1.5 * IQRupper_bound = Q3 + 1.5 * IQRoutliers = df[ (df["income"] < lower_bound) | (df["income"] > upper_bound)]print(outliers)
This method works well as an initial check, especially when the distribution is skewed. However, the IQR rule does not prove that a value is incorrect. It identifies observations that deserve further review.
For normally distributed data, a Z-score can also help identify observations that lie several standard deviations from the mean. For heavily skewed data, robust statistical methods may be more appropriate.
5. Choosing the Right Outlier Treatment
After identifying unusual observations, decide how to handle them based on their cause and effect.
|
Treatment |
When to consider it |
|
Correct the value |
A confirmed data entry or measurement error exists |
|
Remove the record |
The observation is invalid and cannot be corrected |
|
Cap extreme values |
Extreme values distort analysis, and preserving records is important |
|
Apply a transformation |
A skewed distribution needs a suitable analytical transformation |
|
Retain the value |
The observation is genuine and relevant to the problem |
Apply outlier capping
Capping, also called winsorisation in common statistical practice, replaces extreme values with defined upper and lower limits.
df["income_capped"] = df["income"].clip( lower=lower_bound, upper=upper_bound)
This approach preserves the number of records but changes the original values. Keep the original column when possible so that the effect of the treatment can be reviewed.
Log transformations may also help with strongly right-skewed positive variables, such as transaction amounts. The transformation must suit the data and the model being used.
For more techniques, see importance of data cleaning and preprocessing.
6. Avoiding Data Leakage and Distorted Analysis
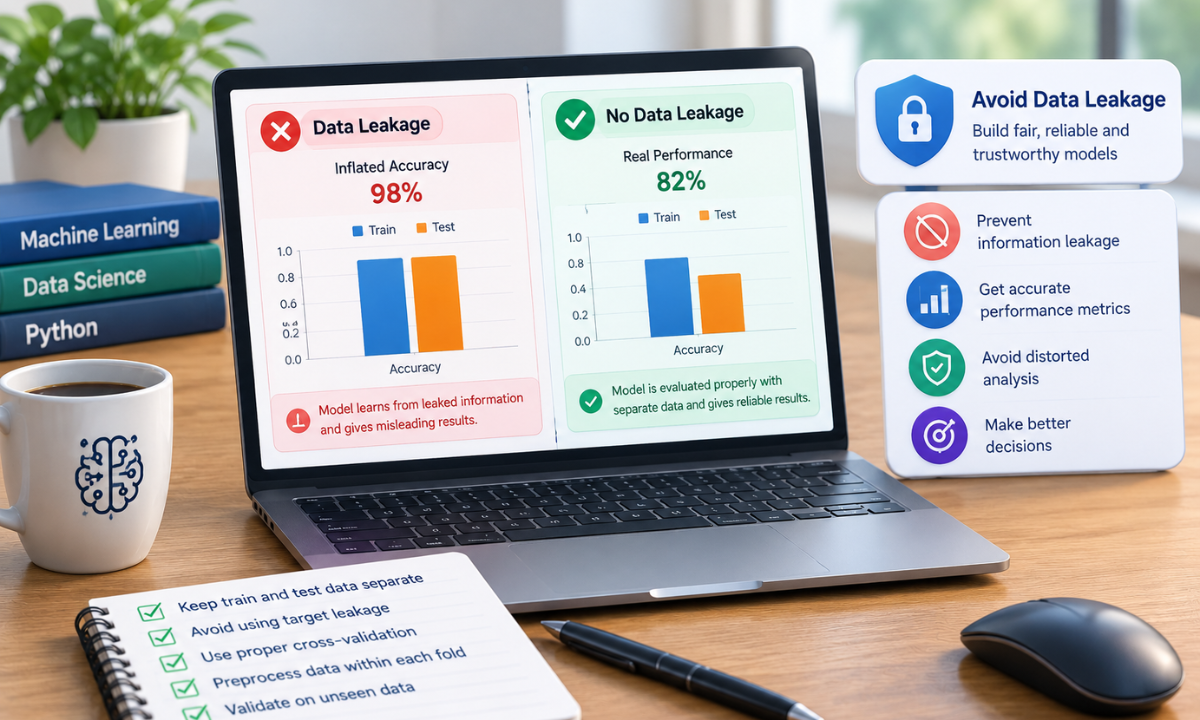
Data leakage occurs when information that would not be available at prediction time influences model training. It can make a model appear more accurate during testing than it performs on new data.
To prevent this, split the dataset before fitting imputation rules, scaling methods, or other transformations. Apply the same fitted transformations to validation and test data.
Scikit-learn pipelines help keep these steps organised and consistent.
from sklearn.pipeline import Pipelinefrom sklearn.impute import SimpleImputerfrom sklearn.preprocessing import StandardScalerpipeline = Pipeline([ ("imputer", SimpleImputer(strategy="median")), ("scaler", StandardScaler())])X_train_processed = pipeline.fit_transform(X_train)X_test_processed = pipeline.transform(X_test)
Here, X_train and X_test represent the training and test feature sets. The pipeline learns the median and scaling parameters from the training data, then applies them to the test data without refitting.
Outlier treatment also requires care. Removing extreme observations may improve certain metrics but can hide important patterns, such as fraudulent transactions or unusually high customer spending.
Compare analytical results before and after treatment to understand how these decisions affect the dataset.
For related concepts, read Data Cleaning vs Data Preparation: What's the Difference?.
7. Best Practices for Reliable Data Cleaning
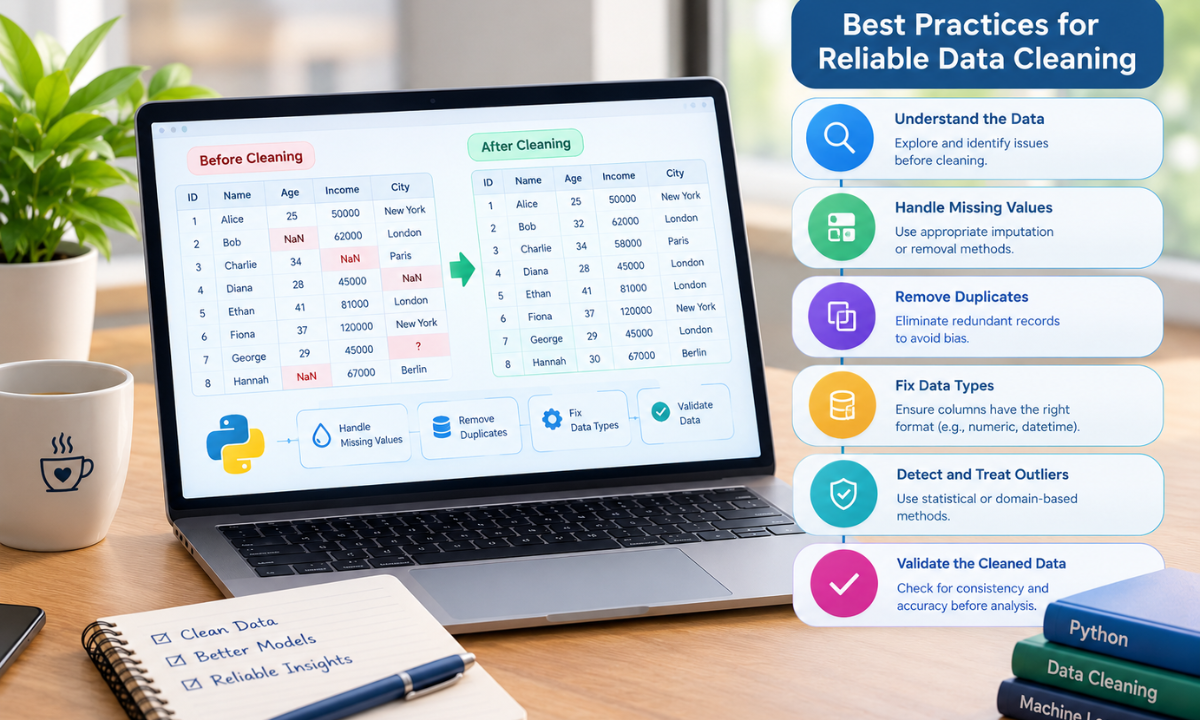
Follow these practices when preparing real-world datasets:
-
Inspect before modifying: Review data types, missing-value patterns, duplicates, and statistical summaries.
-
Understand the source: Investigate why values are missing or unusual before choosing a treatment.
-
Choose methods carefully: Select imputation and outlier techniques based on the variable and analytical objective.
-
Preserve original data: Keep a raw copy so that changes can be checked and reversed.
-
Prevent data leakage: Fit preprocessing steps on training data only.
-
Validate the results: Check missing-value counts, value ranges, distributions, and record counts after cleaning.
-
Document decisions: Record the methods, assumptions, and thresholds used during data preprocessing.
These practices make data cleaning more transparent and help teams reproduce their analysis.
Conclusion
Handling missing values and outliers is an essential part of preparing real-world datasets for statistical analysis and machine learning. Python libraries such as Pandas, NumPy, Matplotlib, and Scikit-learn provide practical methods for identifying incomplete records, applying imputation, detecting unusual observations, and building repeatable preprocessing workflows.
The goal is not to make every dataset look perfect. It is to preserve meaningful information, correct genuine errors, and reduce the risk of misleading conclusions.
Developing these skills also requires an understanding of statistics, exploratory data analysis, and model evaluation. Learners exploring these areas can review the Data Science Course in Bangalore curriculum to understand how Python, data preparation, and machine learning fit into a broader data science workflow.
Reference:

Apponix Academy
Apponix Academy